Migration plans often begin as sensible recommendations and degrade into unexplained work. “Upgrade the authentication service.” “Replace incompatible dependencies.” “Add tests.” “Prepare rollback.” These statements point in the right direction, but they do not tell an engineer what triggered the work, which version is affected, where the evidence lives, how broad the impact is, what completion means, or whether later repository changes invalidate the task.
Evidence-backed planning preserves those connections. It begins with deterministic observations at a known source state, applies versioned migration rules, traces impact through system relationships, and produces tasks with measurable acceptance. Validation results then close the loop by proving whether the finding was resolved in the environment that matters.
This is more than documentation quality. Traceability improves prioritization, review speed, estimate confidence, auditability, and cutover control. It also creates the foundation for responsible use of AI: language models can explain and organize findings without becoming the authority for compatibility or production readiness.
Why migration traceability matters
Modernization programs combine facts with judgments. A lockfile version is a fact at a particular commit. A versioned rule may establish that the package lacks support for the target runtime. The number of affected services comes from dependency paths. Severity is a policy judgment based on production impact and available controls. Effort is an estimate with assumptions. A task is a proposed response. A cutover decision depends on validation evidence.
When these layers are flattened into one spreadsheet cell, reviewers cannot challenge the right thing. They may debate whether a package exists when the real uncertainty is its production path, or accept a precise estimate whose exclusions are hidden. Separating evidence, rule, impact, judgment, and action makes the plan explainable.
Traceability also limits duplicate work. If one internal package blocks twelve services, the evidence chain reveals a shared remediation rather than twelve independent dependency upgrades. It exposes sequencing: the package task must complete and publish a compatible version before service adoption tasks can exit.
During execution, repository state changes. A dependency can be removed, a workflow can switch images, or a new consumer can appear. A task connected to evidence can be automatically marked for review when that evidence changes. An unlinked task remains on the board long after its premise disappears.
No unexplained scores. No unsupported recommendations. Every important conclusion should expose the facts, assumptions, uncertainty, and validation required to trust it.
Build a complete evidence chain
A practical chain begins with a migration rule. The rule defines the source and target transition, applicability conditions, compatible or incompatible versions, relevant configuration, required tests, and supporting technical references. Rules should be versioned because ecosystem knowledge changes. The assessment must record which version produced the finding.
The next link is the observed fact: a declared package range, resolved lockfile version, runtime pin, deprecated API call, Docker base image, workflow action, build-tool version, infrastructure setting, or missing test relationship. Record the repository, commit, path, and line or configuration location where possible. Commit pinning makes the observation reproducible.
Then connect the fact to affected components through a typed dependency graph. A package might reach an internal library, several services, deployment pipelines, and production environments. Preserve the path and relationship type. This supports accurate scope and lets teams remediate at the most effective layer.
The chain continues to a finding. The finding states what the evidence means for this migration, assigns severity and confidence, explains impact, and recommends a response. It should distinguish a deterministic incompatibility from an inferred risk or a manual-review requirement.
Finally, link the finding to one or more migration tasks, owners, dependencies, acceptance criteria, validation gates, and rollback conditions. When the work completes, attach new evidence: upgraded versions, passing builds, contract results, performance comparisons, deployment observations, and approvals. The chain becomes:
Migration rule → observed version or pattern → repository → commit → file or configuration → affected service → finding → migration task → validation gate → verified outcome.
Design findings engineers can act on
A good title is specific and neutral. “Native package compatibility not verified for target runtime” is better than “Critical dependency disaster.” The title names the condition without overstating certainty. The description explains why it matters and which behavior could be affected.
Severity should reflect consequence and control, not merely rule category. A native package in a production request path may be a blocker when no target binary or source-build path exists. The same package in an unused development utility may be low risk. Preserve the applicability evidence that supports the classification.
Confidence describes evidence quality. High confidence might come from a resolved lockfile, parsed workflow, and confirmed production path. Medium confidence may involve conditional imports or environment inference. Low confidence identifies incomplete scope that requires review. Confidence should never be used to hide uncertainty; it should create a discovery task when the unresolved fact can change strategy or effort.
Include affected paths rather than a single repository count. Show how the finding propagates from a dependency or configuration to services and environments. This helps reviewers understand blast radius and choose whether to fix centrally, adapt consumers, or isolate a migration boundary.
Recommended actions should be concrete but not pretend there is only one valid solution. For example: verify a compatible release, test source compilation on the production image, replace the package, or isolate the feature. State the evidence required to close the finding under each accepted path.
A complete finding record
- Stable identifier, concise title, category, severity, and status.
- Repository, commit, file or configuration path, and line where available.
- Observed and target versions with the applicable rule version.
- Affected components, dependency paths, environments, and owners.
- Confidence, evidence limitations, and explicit manual-review questions.
- Impact explanation, remediation options, and closure evidence.
Convert findings into verified engineering tasks
A finding describes a condition; a task changes or proves it. Keep that distinction. One finding may create a central remediation task plus adoption tasks across consumers. Several findings may be resolved by one shared toolchain upgrade. The mapping should be many-to-many when the system demands it.
Every task needs an outcome statement. “Upgrade package X” specifies an activity. “Publish an X version compatible with both source and target runtimes, validate it in representative consumers, and record adoption guidance” describes an outcome that unlocks downstream work. Acceptance criteria should be observable and tied to artifacts or test results.
Include scope and exclusions. Name repositories, packages, services, environments, and user paths covered. State what is not covered and why. This prevents a task from appearing complete while a production-only worker or secondary pipeline remains on the old state.
Attach dependencies and owners. Technical prerequisites come from the graph; organizational prerequisites include approvals, environment access, vendor actions, and specialist review. Assign one accountable owner while recording contributors and reviewers. A shared task with “all teams” as owner usually has no owner.
Define validation at task creation, not after implementation. Include build matrices, unit or integration suites, contract checks, performance thresholds, production probes, security review, and rollback evidence relevant to the finding. Name the expected evidence source so closure can be audited.
Place tasks into migration waves according to dependencies and risk. Safety-baseline and toolchain work precede shared-package remediation; low-risk representative services generate evidence before critical services; production cutover depends on organization-wide gates; cleanup follows the rollback window. The task retains its evidence links even as its wave changes.
Estimate effort without false precision
Migration estimates should be ranges, not single-point promises. A range can express known implementation work and uncertainty around discovery, test stabilization, environment behavior, or external coordination. Use consistent units such as engineer-days while keeping calendar duration separate; dependencies and review capacity affect elapsed time differently from effort.
State assumptions. An estimate for a package upgrade may assume a compatible upstream release, existing contract tests, no schema change, and access to a representative environment. State exclusions such as unrelated refactoring or product changes. List unknowns that can materially move the range, and assign discovery tasks to reduce them.
Connect estimate confidence to evidence coverage. High confidence may require known versions, clear ownership, representative tests, and prior completion of similar work. Lower confidence is appropriate when a native build path, production dependency, or data behavior remains unresolved. Low confidence should influence contingency and sequence, not simply increase the top number without explanation.
Estimate by work category: discovery, code remediation, dependency change, test development, infrastructure, deployment, validation, coordination, and cleanup. This allows early waves to calibrate later ones. If actual test work exceeds the range while code remediation matches it, update the relevant category rather than applying a broad multiplier.
Preserve revisions. When evidence changes the estimate, show the prior range, new range, reason, and source. This builds organizational knowledge and helps stakeholders distinguish planning drift from legitimate scope discovery.
Connect tasks to readiness and cutover gates
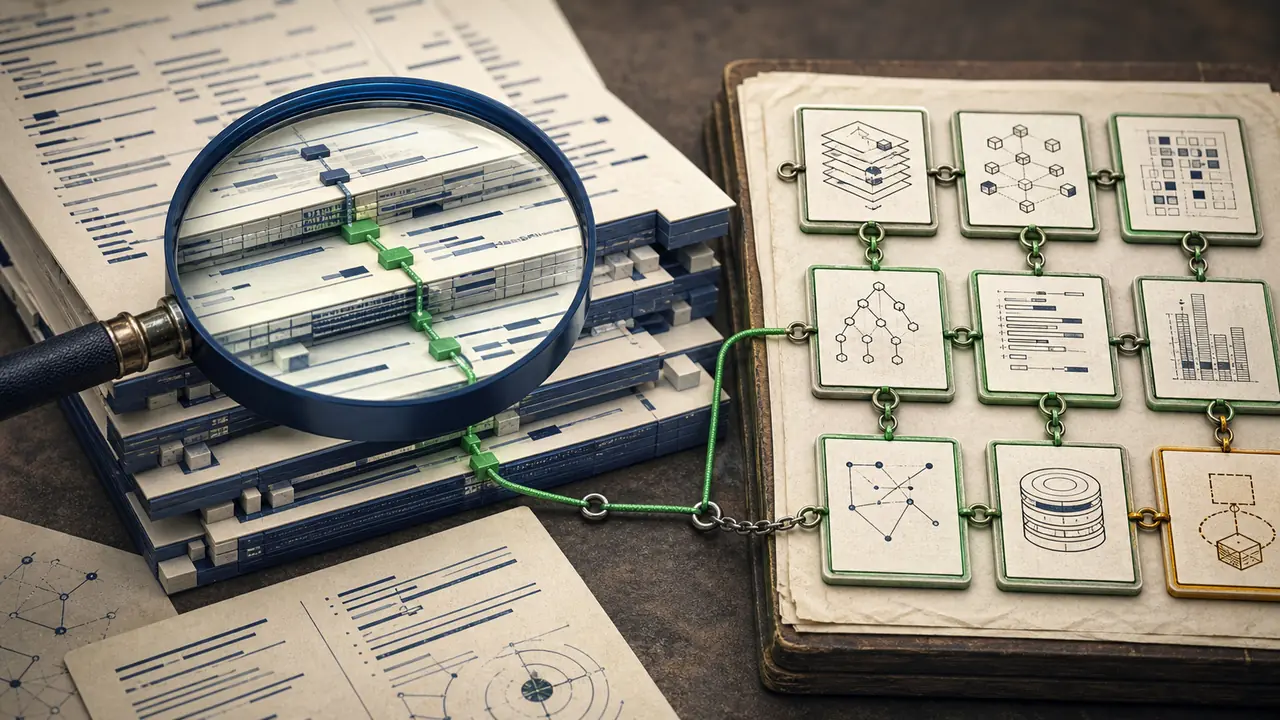
Task completion does not automatically mean migration readiness. A merged dependency change may still await artifact publication, consumer adoption, production validation, or removal of a rollback blocker. Readiness dimensions aggregate closure evidence across dependency, code, tests, infrastructure, delivery, operations, ownership, documentation, and recovery.
Each gate should contain a signal, threshold, environment, observation window, owner, evidence link, and failure action. A build gate can reference immutable workflow runs for scoped commits. A contract gate can name providers, consumers, and versions. A performance gate can compare latency, throughput, and memory against a pinned baseline under a representative workload.
Operational gates include monitoring, alerts, on-call readiness, deployment control, and rollback availability. Security gates can cover permissions, secret handling, image policy, and required review. Approval gates should identify the accountable role and inputs used, not merely record a checkbox.
Use status language in addition to color: passed, at risk, blocked, or pending. Explain why a gate has its status. A pending performance test is different from a failed threshold, and both differ from missing test infrastructure. That distinction guides the next task.
At cutover, produce a coherent snapshot. The decision record should identify scoped commits and artifacts, open risks, accepted exceptions, gate results, rollback state, owners, and observation plan. This is the evidence package behind a human-controlled go or no-go decision.
Use AI to explain, organize, and assist
AI is valuable when a migration produces hundreds of technical observations. It can summarize deterministic findings for different audiences, group related work, draft task descriptions, suggest wave sequencing, explain dependency paths, and prepare rollout or rollback text. These uses reduce coordination overhead while preserving technical authority in verifiable sources.
AI should not independently decide whether a dependency is compatible, whether security requirements are satisfied, whether an untested patch should merge, whether a migration succeeded, or whether production traffic should switch. Those decisions require versioned rules, executable validation, policy, and accountable human review.
Generated content must retain citations to internal evidence. If a summary says a shared package blocks five services, reviewers should be able to open the paths that support that count. If AI proposes a wave, its prerequisites should trace to graph edges and finding status. Unsupported language should never become a blocker or a readiness claim.
Human corrections should improve the evidence model. When an engineer identifies a false edge, environment exception, or more precise compatibility rule, capture the correction with provenance and apply it consistently. The goal is not to preserve an AI answer; it is to improve the organization’s migration intelligence.
Maintain evidence while repositories change
An assessment is a snapshot, while migration execution happens over time. New commits can resolve findings, introduce dependencies, change ownership, or invalidate test evidence. Continuous rescanning compares the current state with the last pinned snapshot and updates the chain deliberately.
Show deltas: added and removed components, version changes, new and resolved findings, changed dependency paths, readiness movement, estimate revisions, and assumptions requiring review. Explain each material score change. A readiness percentage without a causal delta is difficult to trust.
Do not close a finding only because its original text disappeared. Determine whether the condition was remediated, the component was removed from scope, the rule changed, or analysis lost visibility. Each reason has a different implication. Preserve history so teams can reconstruct the decision.
Invalidate downstream tasks when their evidence changes. A new consumer may expand scope; a package replacement may make an old remediation obsolete; a pipeline change may require fresh validation. Notify owners with the changed path and recommended review rather than generating undifferentiated alerts.
After cutover, compare plan with outcome. Record actual effort, observed blockers, incidents, gate effectiveness, rollback performance, and cleanup completion. Feed reusable facts into migration rules and estimate calibration. Evidence-backed planning becomes stronger when completed migrations improve the next assessment.
Design exports that preserve context
Engineering teams often execute work in GitHub Issues, Jira, or Linear. Exported tasks should keep stable links to findings and evidence rather than copying a one-time description. Include scope, owner, prerequisites, acceptance criteria, estimate range, wave, and current gate relationship. When a rescan changes the source condition, update the linked record or request review while preserving discussion and history.
Reports for leadership can summarize readiness, critical paths, and effort without removing uncertainty. Let readers move from a dimension score to its blockers, from a blocker to affected services, and from a service to repository evidence and owned tasks. Different levels of detail should be views of one model, not independently maintained narratives. This preserves a shared truth while making it usable at each decision level.
Define access according to responsibility. Repository evidence may contain sensitive paths or configuration, while program stakeholders still need aggregated decisions. Preserve the same identifiers and calculations across views, but reveal source details only to authorized roles. Audit evidence access, task changes, exception approvals, and cutover decisions. Explainability is strongest when it operates alongside least privilege rather than encouraging uncontrolled copies of source-derived reports.
Evidence-backed planning checklist
- Every observation is pinned to repository, commit, path, and parser or rule.
- Migration rules are versioned and state applicability and closure conditions.
- Typed dependency paths connect findings to affected services and environments.
- Severity and confidence are separate, explained, and reviewable.
- Manual-review questions are explicit and assigned.
- Findings map to outcome-based tasks with accountable owners.
- Tasks include scope, exclusions, prerequisites, acceptance, and rollback.
- Effort uses ranges, assumptions, unknowns, and confidence.
- Validation gates name signals, thresholds, evidence sources, and failure actions.
- AI-generated explanations retain links to deterministic facts.
- Rescans explain deltas and invalidate affected downstream work.
- Actual outcomes calibrate future rules, estimates, and sequencing.
Conclusion
Evidence-backed migration planning creates an unbroken line from technical fact to production decision. Versioned rules interpret reproducible repository observations. Dependency paths define impact. Findings make risk and confidence explicit. Tasks describe owned outcomes. Validation gates prove completion, and continuous rescanning keeps every link aligned with current system state.
This model gives engineers room to challenge assumptions without losing context and gives leaders a readiness view grounded in inspectable work. AI can make the model easier to navigate, but deterministic analysis, executable validation, and human control remain authoritative. The result is a migration plan that teams can explain, execute, verify, and improve.
Connect every recommendation to proof.
CutoverGrid traces migration rules through repositories, dependencies, tasks, owners, and cutover gates so engineering teams can act on evidence.