A monorepo can simplify a runtime migration because code, dependency metadata, ownership, and pipelines are visible in one place. It can also amplify the migration’s difficulty. Hundreds of workspaces may share one lockfile, one build graph, one release mechanism, and a small set of platform maintainers. A change that is local in source code can affect installation for everyone. A shared package update can propagate across dozens of deployables before all consumers are ready.
The right plan uses the monorepo’s visibility and automation while preserving containment. It treats workspaces and deployables as distinct units, sequences shared foundations before consumers, supports controlled runtime coexistence where necessary, and continuously recalculates impact as branches merge. This guide lays out that plan from initial discovery through production cutover.
Understand what makes monorepo migrations different
A monorepo is not one application. It is a repository boundary containing a graph of libraries, services, tools, jobs, tests, and infrastructure. These components may have independent owners and deployment schedules even when they share source control. Planning the migration as one giant version bump ignores operational autonomy; planning every workspace separately ignores shared installation and build constraints.
Coupling appears at several layers. A workspace dependency graph connects internal packages and applications. A single lockfile may select transitive versions for all of them. Root configuration controls TypeScript, linting, testing, task execution, and package-manager behavior. CI optimization decides which tasks run after a change. Deployment pipelines may publish many artifacts from one commit. Teams can therefore be isolated at runtime but tightly coupled during build and release.
The first planning principle is to identify these coupling points and decide which should remain shared during the migration. Moving every workspace simultaneously can produce a long-lived integration branch and an enormous validation surface. Allowing arbitrary per-workspace runtimes can fragment developer experience and make root tooling unreliable. Most successful programs use a bounded transition period with deliberate compatibility rules.
Plan around deployables and shared foundations
Use deployable services as cutover units, internal packages as dependency units, and root tooling as a shared platform. Each has different readiness evidence and a different migration sequence.
Map workspaces, deployables, and ownership
Begin by parsing the actual workspace configuration and lockfile. Identify every package root, package name, versioning model, private or published status, declared runtime range, build command, test command, and internal dependency. Detect references that bypass the package manager, such as path aliases, relative imports across workspace boundaries, generated code, vendored sources, and custom task-runner configuration.
Then identify deployables. A workspace can produce several jobs or functions, and several workspaces can combine into one image. Connect applications, APIs, workers, scheduled tasks, command-line tools, and serverless functions to their entry points, Dockerfiles, deployment manifests, environments, and runtime versions. Do not count documentation packages or development utilities as production services, but do not exclude them from toolchain readiness if they execute during the build.
Create a directed graph of internal dependencies. The direction must reflect consumption: if the orders service imports the database package, the service depends on the package. Identify strongly connected components, because cycles prevent a simple leaf-to-root sequence. Find highly connected packages whose changes affect many consumers, including logging, telemetry, configuration, authentication, schema, UI, and API clients.
Add team ownership at both package and deployable level. Root ownership files are helpful but may not reflect operational responsibility. Compare them with service catalogs, deployment permissions, and on-call rotations. Assign an owner to root tooling, the lockfile, build images, CI templates, and release automation. These shared components often create the most work and need dedicated capacity.
- Inventory every workspace and classify it as deployable, shared package, tool, configuration, or documentation.
- Resolve internal and external dependency versions from the lockfile.
- Map each production artifact back to workspace inputs and pipeline definitions.
- Locate root configuration inherited by many packages.
- Identify dependency cycles, central packages, and cross-team ownership paths.
- Pin the entire assessment to a commit and record the rule version used.
Define a target runtime policy for the whole repository
Specify the target runtime precisely: major and minimum patch version, supported operating systems and CPU architectures, container image family, package manager and version, and the date after which the previous runtime is unsupported in the repository. Decide whether the same policy applies to development tools, build jobs, tests, and production applications. Exceptions should be explicit, owned, and time-bound.
A monorepo needs a clear source of truth. Runtime versions can appear in engine declarations, version-manager files, package-manager settings, Dockerfiles, CI matrices, task-runner images, deployment manifests, and developer containers. Define which declaration is authoritative and add automated consistency checks. Otherwise, different surfaces will drift immediately after the migration.
Separate runtime modernization from adjacent changes unless they are technically inseparable. Changing module format, test frameworks, bundlers, lint rules, and compiler settings in the same program expands the failure search space. If the target runtime requires these updates, represent them as distinct workstreams with their own evidence. If they are optional, defer them or schedule them in a later cleanup wave.
Define coexistence rules. Can a package support both source and target runtimes temporarily? Can root tooling run on the target while an application still deploys on the source? Will the lockfile remain installable under both? The answers determine whether the migration can proceed in waves or needs a narrower synchronized cut. Test the policy rather than relying on engine declarations alone.
Establish compatibility and validation baselines
Run a clean installation from the pinned commit under the current runtime and preserve the result. Capture package-manager output, lifecycle scripts, downloaded binaries, cache behavior, build artifacts, and test outcomes. This establishes whether existing failures predate the migration. Repeat under the target runtime in an isolated environment that matches production architecture and operating system.
Scan direct and transitive dependencies for runtime constraints, deprecated APIs, unsupported versions, and native modules. In a shared lockfile, a single incompatible transitive component can affect many workspaces. Trace every finding upward to actual consumers. This distinguishes a package present only in a development tool from one embedded in critical production services.
Inventory validation by workspace and deployable. Record unit, integration, contract, end-to-end, performance, and smoke tests, along with target-runtime results and gating behavior. A root test command may skip projects based on change detection. Verify that the migration’s configuration changes cause every affected task to run, even if source files did not change inside a workspace.
Capture baseline operational behavior for production services: error rates, latency percentiles, throughput, memory, CPU, event-loop delay, restarts, queue lag, and critical business outcomes. These measurements define comparison thresholds for canaries. Without a baseline, teams can observe charts but cannot make an objective cutover decision.
Choose between synchronized and incremental migration
A synchronized migration changes the root runtime and all workspaces together. It minimizes the duration of dual support and can be appropriate for a small monorepo with one release train, strong tests, and tightly coordinated ownership. Its disadvantages are a large review surface, difficult failure isolation, and limited ability to learn from early deployables before critical ones move.
An incremental migration allows workspaces or deployables to move in waves. It reduces simultaneous operational exposure and lets teams apply lessons from pilots. It requires temporary compatibility across runtimes, a reliable way to select runtime per task or image, and discipline to prevent the transitional state from becoming permanent. Root installation and tooling must work across the supported matrix.
A hybrid strategy is common. Move root tooling, the package manager, lockfile, and shared build infrastructure to a target-compatible state first. Make shared libraries dual-compatible where practical. Then migrate deployables in dependency-aware waves, each producing an artifact with an explicit runtime. Finally, remove source-runtime compatibility after every consumer has cut over.
Document why the strategy fits repository scale, dependency structure, deployment autonomy, team capacity, and recovery requirements. Define a maximum coexistence period and an enforcement mechanism. Temporary matrices, overrides, and compatibility flags should have owners and deletion conditions from the day they are introduced.
Upgrade shared packages before their consumers
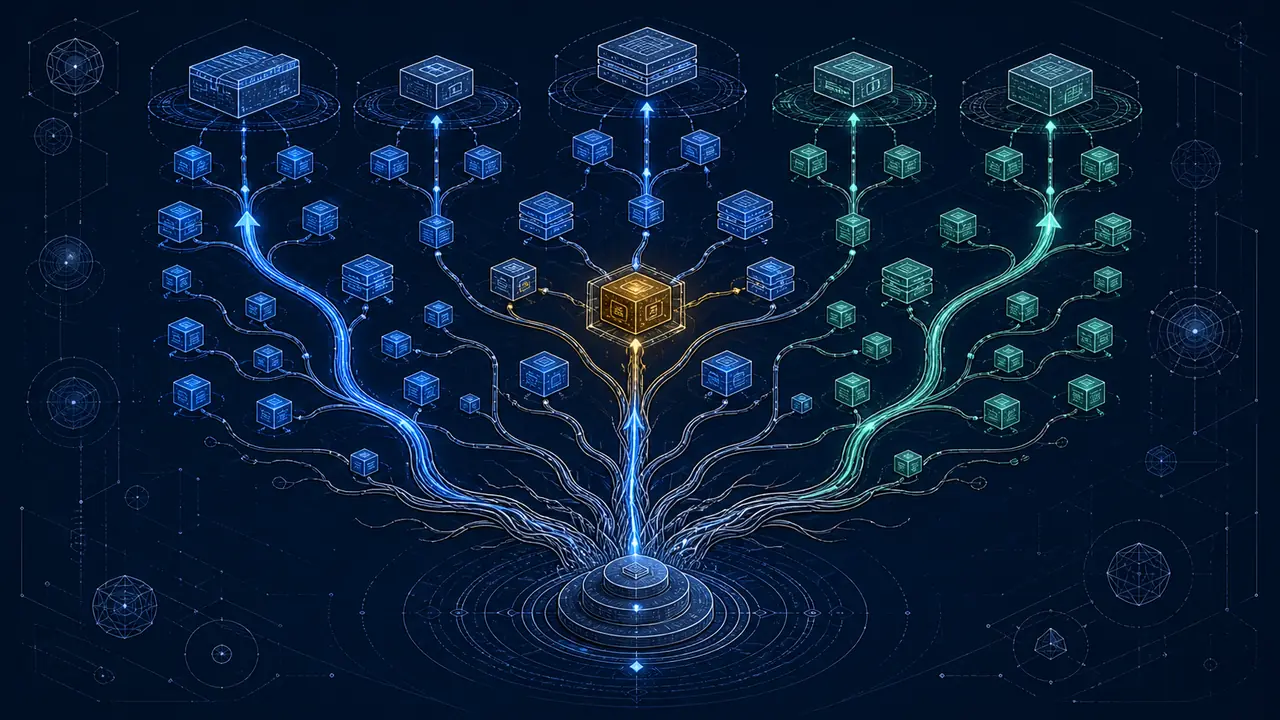
Shared internal packages determine the migration’s critical path. For each package, establish target-runtime compatibility, source-runtime compatibility during transition, consumer count, release model, and validation strength. Central packages deserve priority because one fix can unblock many applications, but they also deserve careful rollout because a regression propagates broadly.
Test shared packages with representative consumers. Package-local unit tests cannot reveal module-resolution differences, peer dependency conflicts, bundler behavior, initialization order, or integration assumptions. Select consumers that cover major frameworks, deployment models, and operational criticality. Use candidate versions or workspace references without prematurely publishing a breaking default.
When a package must make a breaking change, define a compatibility interface. This might be a new major version, adapter, dual export, feature flag, or temporary branch. Map which consumers use each path and sequence them. Avoid global lockfile overrides as a substitute for consumer validation; overrides can hide incompatible expectations and make local success differ from published behavior.
Update package metadata truthfully. Runtime engine ranges, peer requirements, exports, and type declarations should match the versions actually tested. Add a CI matrix while dual support is promised. Once the source runtime is retired, remove its lane and adjust policy so new changes do not accidentally restore unsupported compatibility obligations.
Adapt CI, builds, and developer workflows
Root pipelines need explicit runtime selection. Audit hosted actions, custom scripts, task runners, code generators, linters, formatters, test runners, and release tools. Some vendor actions bundle a runtime internally; others execute repository code under the runner’s installed version. Classify each so the team changes the right layer.
Ensure affected-project optimization remains correct. A runtime or root configuration change can affect every workspace even when task hashing sees no local source difference. Invalidate caches deliberately and run a complete build and test at key milestones. Compare clean and cached execution to detect artifacts that were produced under the old runtime but reused under the new one.
Make local development predictable. Update version-manager files, developer containers, onboarding instructions, editor tasks, and pre-commit tools. Fail quickly with a clear version message when a command uses an unsupported runtime. During coexistence, provide wrapper commands or documented task selection so engineers do not manually switch versions in an error-prone sequence.
Keep production artifacts explicit. Label images and deployment metadata with runtime version and source commit. Avoid mutable base tags. Confirm architecture-specific native dependencies during build, scan the final image, and preserve the previous artifact for rollback. Reproducibility is especially important in a monorepo because one commit may produce many independently deployed artifacts.
Sequence migration waves by graph and operating risk
Wave zero establishes safety: inventory, ownership, baseline tests, observability, rollout controls, and rollback. Wave one prepares shared tooling and enables the target runtime without removing the source. Wave two upgrades central internal packages and validates representative consumers. Later waves migrate deployables from low operational consequence toward critical services, while respecting dependency order.
Select pilots for learning value. A pilot should use common shared packages, exercise typical build and deployment paths, have meaningful traffic or workload, and be easy to roll back. An obscure utility with no monitoring may be low consequence but teaches little. Record pilot findings and update rules, templates, estimates, and validation requirements before the next wave.
For each wave, define entry criteria, included deployables, package prerequisites, owners, tasks, test gates, rollout steps, observation window, and rollback conditions. Reserve capacity for shared-platform maintainers who will support many waves. Avoid placing services with the same failure domain in one cohort when independent comparison is possible.
Rescan the monorepo after merges. Show newly introduced runtime pins, dependencies, native modules, and affected consumers. Recalculate wave readiness and critical paths. The graph can change while execution is underway; the plan must respond to code rather than preserving a frozen spreadsheet.
Verify each deployable and complete repository cutover
A monorepo migration reaches production one deployable at a time. Require reproducible target artifacts, relevant tests, contract verification, performance thresholds, cohort-level monitoring, rollback availability, on-call coverage, and approval appropriate to service criticality. Increase traffic gradually and compare target and source cohorts using defined signals.
Rollback must account for shared package and data compatibility. The previous application image may not be safe if a migration changed a schema or protocol. Use expand-and-contract patterns and maintain backward compatibility across the observation window. Test traffic reversal and artifact restoration before relying on them.
Repository-level completion happens after every production deployable runs the target, all required jobs and tools use supported versions, shared packages no longer promise obsolete compatibility, and temporary mechanisms are removed. Delete old CI lanes, runtime selectors, patches, and overrides. Refresh templates and policy checks so new workspaces inherit the target automatically.
Finish with a program review. Compare predicted and actual effort, blockers, critical paths, test escapes, and operational outcomes. Identify which repository relationships were missing and which shared controls created leverage. Incorporate those lessons into discovery and future Migration Packs. A monorepo makes this institutional learning particularly valuable because improvements become available to every workspace.
Measure the repository after cleanup as well. Confirm that every active workspace declares or inherits the supported runtime, every production artifact exposes its runtime identity, and policy prevents an obsolete version from returning through a new package or copied pipeline. Review dependency cycles that complicated sequencing and ownership gaps that slowed decisions. The migration creates a rare, high-quality view of the repository’s real architecture; use it to reduce coupling and clarify boundaries rather than discarding it when the final service moves.
Keep the operational graph attached to the source model. When a new workspace is created, it should inherit build, test, image, and ownership controls automatically. When a shared package changes its runtime policy, affected consumers should be identified before merge. These controls transform a completed migration into durable modernization capability and reduce the discovery cost of the next major runtime release.
Retain a concise exception register for anything that cannot follow the common policy. Each exception needs a workspace, owner, business reason, supported runtime, compensating validation, and removal date. Check it in normal pull-request workflows. Visible exceptions allow necessary autonomy while preventing temporary coexistence from becoming invisible fragmentation across the repository.
Use shared structure to create controlled change
A monorepo runtime migration succeeds when teams treat the repository as a connected system without treating it as one indivisible deployment. Map workspaces, packages, deployables, pipelines, environments, and owners. Establish an explicit target policy, validate shared foundations, choose a bounded coexistence strategy, and sequence consumers through dependency-aware waves.
The result should be more than a newer runtime. It should leave behind reproducible builds, clearer ownership, stronger consumer validation, explicit production gates, and policy that prevents drift. With those controls, the monorepo becomes an advantage: one evidence model can coordinate many teams while every deployable retains a safe, observable cutover path.
Coordinate every workspace, package, and cutover
CutoverGrid maps monorepo impact, shared blockers, ownership, effort, migration waves, and production evidence from one commit-pinned assessment.
Book a CutoverGrid demo See how CutoverGrid works