Every major software migration eventually reaches the same operational question: should the organization move in controlled increments or switch the whole affected estate in one coordinated event? The familiar labels are phased migration and big-bang migration, but the real choice is more precise. Teams are deciding how much change to expose at once, how quickly they can detect a failure, what they can reverse independently, and how much temporary complexity they are prepared to operate.
A runtime or framework upgrade may look local when viewed in a single repository. In production, it often spans shared libraries, container images, continuous integration jobs, deployment templates, service contracts, observability rules, and ownership boundaries. A strategy that works for one application can become unsafe across dozens of services. Conversely, dividing a tightly coupled system into artificial waves can create months of compatibility code and dual-operation cost without reducing meaningful risk.
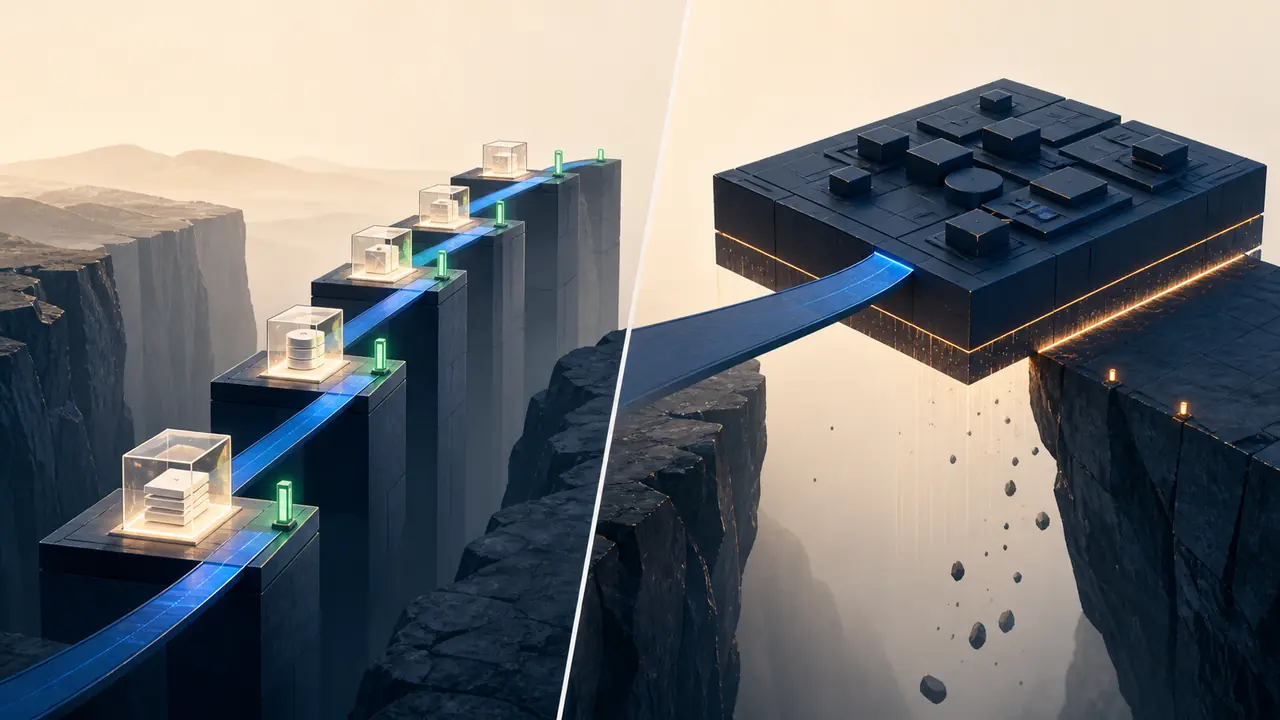
The strongest decision therefore starts with evidence rather than preference. It uses a commit-pinned inventory, an impact graph, explicit cutover gates, quantified unknowns, and a tested rollback model. This article presents a practical framework for making that decision and translating it into an executable plan.
The decision beneath the labels
A phased migration changes bounded parts of the system over a sequence of releases or migration waves. Each wave has its own scope, entry criteria, validation, observation period, and completion conditions. Old and new states coexist for some period. That coexistence can be as simple as different services running different runtime versions, or as involved as dual writes, protocol translation, compatibility adapters, and versioned data contracts.
A big-bang migration coordinates the affected system around one cutover boundary. Preparation can still take months and include extensive rehearsal, but the production transition happens as one event. The defining characteristic is not speed of preparation. It is that the old and new states are not intended to operate independently for a prolonged period after cutover.
Neither approach is inherently mature or reckless. A phased migration without reliable compatibility boundaries merely spreads uncertainty across more releases. A big-bang migration with a reversible deployment artifact, a rehearsed runbook, complete observability, and strong contract coverage can be tightly controlled. The decision should be framed as an allocation of risk: concentrated operational risk in a shorter window versus distributed compatibility and coordination risk over a longer interval.
Choose the smallest independently verifiable unit of change. If no meaningful unit can be isolated, invest in creating a boundary or prepare a coordinated cutover with stronger gates.
How a phased migration works
A well-designed phased migration begins by establishing a safety baseline. Teams identify representative builds, test suites, service-level indicators, performance thresholds, deployment procedures, and rollback artifacts before changing the target technology. This baseline prevents a common failure mode: discovering during the migration that nobody can distinguish a new regression from an existing weakness.
The next waves typically prepare the toolchain and shared foundations. Continuous integration runners, base container images, language compilers, package managers, test frameworks, linters, and deployment templates may need to support both source and target states. Shared internal packages are upgraded before dependent applications when their compatibility determines the feasible sequence. Low-risk or stateless services then act as controlled proving grounds, followed by critical services after evidence accumulates.
The main advantage is containment. A defect affects a bounded set of workloads, and telemetry from earlier waves improves later decisions. Teams can revise estimates, strengthen rules, and update runbooks using observed behavior. The organization also avoids scheduling every owner for a single high-pressure event. Where repositories have clear interfaces and deployments are independent, this strategy aligns migration work with normal delivery.
The main cost is coexistence. Different runtime versions can require matrix testing. Shared libraries may need to support two environments. Schemas and messages must remain compatible across mixed versions. Operational documentation becomes stateful: a runbook may depend on which wave a service has reached. Every temporary bridge is additional software with an owner, a removal condition, and a failure mode. If the program lacks continuous rescanning, its central plan can drift as teams merge unrelated changes.
Phasing is strongest when services are independently deployable, contracts are explicit, traffic can be segmented, and rollback can happen at the wave level. It is weaker when components share process memory, make coordinated schema assumptions, or depend on a single deployment artifact. The number of repositories is not the deciding factor; the shape of their runtime coupling is.
Conditions that favor phasing
- Services have stable, versioned, or backward-compatible interfaces.
- Deployment units can be released and rolled back independently.
- Traffic can be routed to cohorts, canaries, regions, or tenants.
- Shared packages can support both source and target runtimes temporarily.
- Telemetry can compare old and new behavior at the wave boundary.
- Teams can absorb the operational cost of a mixed estate.
How a big-bang migration works
A disciplined big-bang migration separates preparation from transition. Teams first make the new state reproducible: target runtime images are immutable, dependencies are resolved from controlled lockfiles, infrastructure changes are reviewed, and all relevant repositories are pinned to known commits. They rehearse the runbook in an environment that reflects production topology and data volume closely enough to expose timing, capacity, permission, and ordering failures.
The cutover itself is governed by a control timeline. It names the decision authority, change freeze, go or no-go checkpoints, commands or deployment actions, expected durations, health queries, abort thresholds, rollback trigger, and communication channels. Each gate must produce an observable result. “Verify the service” is not a gate; “error rate remains below the agreed threshold for the observation window, contract probes pass, queue lag remains within budget, and on-call confirms dashboards” is closer to an executable condition.
The primary advantage is state simplicity. The organization avoids maintaining compatibility between old and new application states for weeks or months. This is valuable when schemas, protocols, generated clients, or shared runtime assumptions must move together. A coordinated event can also shorten the period in which security patches or vendor support policies differ across the estate.
The primary risk is correlated failure. A gap in analysis can affect every migrated component simultaneously. Operational pressure is concentrated, and rollback may take longer than expected if data or infrastructure changes are not symmetrical. A broad cutover also creates a larger evidence surface: every repository, pipeline, environment, owner, and validation dependency must be ready at the same time.
Conditions that favor a coordinated cutover
- The system has strong coupling that cannot be safely versioned.
- Old and new states cannot process the same data or protocol concurrently.
- A short maintenance boundary is acceptable to product and operations.
- The full transition can be rehearsed with representative production conditions.
- A complete rollback can be executed within the recovery objective.
- Owners and decision makers can participate in one controlled event.
Use explicit criteria, not organizational instinct
A strategy review should score evidence across several dimensions. Start with blast radius: how many user journeys, services, data stores, and operational teams can one failed release affect? Then evaluate reversibility. Deployment rollback is only one layer. The team must know whether schemas, queue messages, caches, generated artifacts, background jobs, and externally visible contracts remain compatible with the restored application.
Consider detection latency. If a regression is visible immediately in build output or synthetic checks, a larger unit of change may be tolerable. If it appears only under end-of-month workloads, long-running jobs, rare account states, or delayed events, a phased rollout creates valuable observation time. Detection latency should be paired with time to mitigate. Fast detection does not help when rebuilding a native dependency or restoring a data snapshot takes hours.
Measure compatibility cost rather than merely acknowledging it. List every adapter, dual-version library, versioned endpoint, flag, schema bridge, and matrix test required by a mixed estate. Assign an owner and removal gate to each. A phased program becomes less attractive as this temporary architecture grows, particularly when the same specialists must maintain it while completing the migration.
Assess organizational concurrency. Independent teams with stable interfaces can own waves and proceed under shared policy. A small group that controls most dependencies may become a bottleneck if every wave requires its approval. On the other hand, a single cutover that depends on many time zones and vendors can accumulate coordination failure even if the technology is ready.
Finally, examine evidence confidence. A dependency found in a lockfile at a pinned commit is high-confidence evidence. A service relationship inferred from naming conventions is weaker. Unknown ownership, unavailable performance baselines, missing contract tests, and undocumented production jobs should reduce confidence. Low confidence does not automatically dictate phasing, but it does require discovery work before the cutover strategy can be trusted.
Let dependency topology define migration boundaries
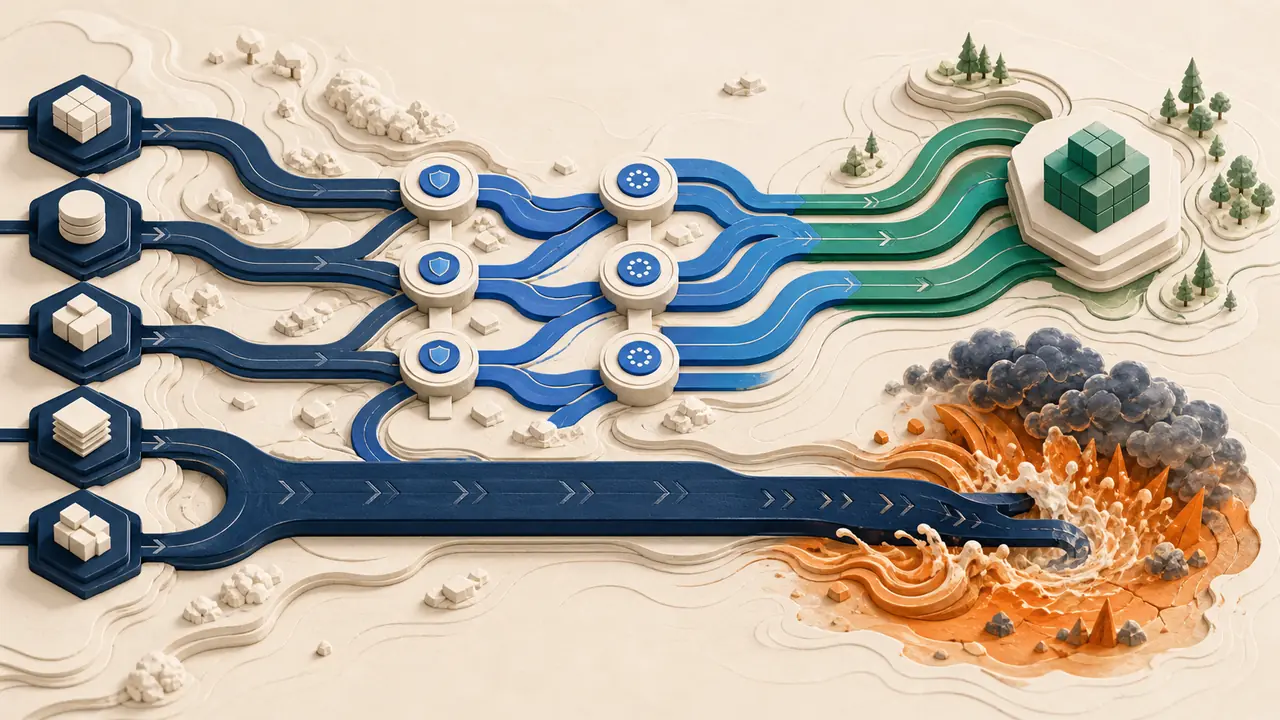
A dependency graph turns an abstract estate into a sequence problem. Nodes represent deployable services, applications, packages, databases, pipelines, or infrastructure components. Directed edges represent relationships such as runtime dependency, build dependency, API consumption, data ownership, shared deployment, or operational approval. Edge types matter because they imply different sequencing rules.
Shared packages often form the earliest critical path. If ten services depend on one internal library that does not support the target runtime, migrating the leaf services first creates repeated exceptions. The better first wave updates and validates the package, publishes a compatible version, and proves it on selected consumers. Conversely, a library already compatible across both runtimes can act as a bridge and enable gradual movement.
Cycles deserve special treatment. Two services may depend on each other through synchronous APIs, shared schemas, or coordinated deployments. A graph that only shows repository imports can miss these runtime cycles. Teams should either break the cycle through a compatible contract, move the strongly connected group as one wave, or accept a coordinated cutover for that boundary. Pretending cyclic nodes are independent produces plans that look orderly but cannot be executed.
Ownership edges are equally important. A technically separable service is not independently migratable when its deployment requires another team’s manual approval, a central infrastructure change, or a vendor action. The execution graph must combine technical and organizational dependencies so the schedule reflects how work actually moves.
Validation strength and rollback depth
Cutover strategy should follow the weakest critical validation layer. Unit tests show that local logic behaves as expected. Integration tests verify adapters and infrastructure dependencies. Contract tests protect interactions between independently released components. Performance tests expose runtime, garbage collection, connection-pool, serialization, and concurrency changes. Production probes and service-level indicators confirm behavior under real traffic. A high unit-test count cannot compensate for absent contract or operational checks.
Define gates as decisions with evidence, not activities. Each gate needs a signal, threshold, observation window, evidence source, responsible owner, and failure action. For example, a performance gate may require the target build to remain within an agreed latency and memory envelope under a representative workload. The associated failure action might block promotion and return the issue to the runtime workstream.
Rollback planning must cover application, configuration, infrastructure, and data. Confirm that the previous image is available, signed, deployable, and compatible with current configuration. Verify that secrets and feature flags can return to the earlier state. For database changes, prefer expand-and-contract patterns when possible: add compatible structures, migrate usage, observe, and remove old structures only after rollback is no longer required. If a migration is irreversible, the recovery plan is a forward repair, and the organization should label it honestly.
A phased strategy needs rollback at each wave boundary. A big-bang strategy needs a full-system restoration sequence and a clear last responsible moment for invoking it. In both cases, rehearse the action. A document that has never been executed is a hypothesis, especially when access permissions, artifact retention, DNS timing, data restoration, or infrastructure state affect recovery.
The previous artifact either exists and can be deployed by an authorized operator within the recovery objective, or rollback is not ready. A filename in a runbook is not sufficient evidence.
Hybrid patterns are usually more precise
Many real programs use a hybrid strategy because the estate contains several dependency shapes. Shared tooling and internal libraries may move in phases, while a tightly coupled service cluster uses one coordinated cutover. A database can use expand-and-contract changes over multiple releases even when application traffic switches in one event. Regions may move sequentially while every service inside a region changes together.
A canary is another hybrid boundary. The deployment artifact changes broadly, but exposure is phased by traffic. This provides rapid behavioral evidence without operating different source branches. Blue-green deployment creates two environment states and makes traffic switching reversible, provided data and external side effects remain compatible. Feature flags can separate deployment from activation, but they are not a substitute for runtime compatibility and require explicit cleanup.
The useful question is therefore not “phased or big bang?” at program level. Ask it for each migration boundary: package, service, cluster, data store, environment, region, tenant cohort, and user capability. Document why the chosen boundary is independent, how it is observed, and what reverses it. The resulting plan may contain several cutover patterns governed by one set of evidence and approval rules.
Turn the strategy into an executable cutover plan
Begin with a commit-pinned scope. Record repositories, branches, commits, deployment units, environments, runtime versions, package managers, base images, CI workflows, infrastructure definitions, and owners. Pinning matters because migration evidence decays as code changes. A plan should always state the source state from which its findings were derived.
Next, classify findings as blockers, risks, or manual-review items. A blocker prevents the target state or makes cutover unsafe. A risk can be accepted with controls. A manual-review item identifies evidence that deterministic analysis cannot resolve. Each finding should link to a repository, commit, file or configuration path, rule, affected component, confidence level, and recommended action.
Build waves from dependencies, not arbitrary team batches. Establish the safety baseline first, prepare shared toolchains, upgrade foundational packages, prove low-risk services, migrate critical workloads, perform production cutover, and remove temporary compatibility structures. Every wave needs entry criteria, tasks, owners, dependencies, acceptance criteria, validation gates, rollback conditions, and an observation period.
Create a decision record for the strategy. Include alternatives considered, the evidence used, unresolved unknowns, compatibility cost, expected operational load, and the conditions that would trigger a strategy change. If a shared package loses dual-runtime support or a contract test exposes tighter coupling, the plan should be allowed to change rather than forcing new evidence into an obsolete sequence.
Rescan continuously. Dependency updates, new services, pipeline edits, and infrastructure changes can introduce blockers after the initial assessment. Compare each scan to the prior commit-pinned snapshot. Show resolved findings, new findings, readiness movement, estimate changes, and invalidated assumptions. This keeps the migration plan connected to the system teams are actually shipping.
Cutover strategy review checklist
- Scope is pinned to known repository commits and deployment configurations.
- Technical, runtime, data, operational, and ownership dependencies are mapped.
- Migration boundaries are independently deployable or explicitly grouped.
- Compatibility bridges have owners and removal conditions.
- Every gate has a signal, threshold, evidence source, and failure action.
- Rollback covers artifacts, configuration, infrastructure, and data.
- The runbook has been rehearsed under representative conditions.
- Decision authority and communication paths are unambiguous.
- Continuous rescanning protects the plan from repository drift.
Conclusion
Phased and big-bang migrations are tools for controlling different kinds of risk. Phasing limits immediate blast radius and creates learning opportunities, but it introduces compatibility work and a longer period of mixed operation. A coordinated cutover keeps the target state simpler, but it concentrates operational exposure and demands broader readiness at one moment.
The defensible choice comes from system evidence: dependency topology, independent deployability, contract strength, detection latency, recovery time, data reversibility, organizational ownership, and the cost of coexistence. Use those facts to choose a boundary, then attach tasks, gates, owners, thresholds, and rollback conditions. When the evidence changes, rescan and revise the decision. That is how a cutover strategy becomes an engineering control rather than a calendar event.
Choose a strategy from evidence, not assumptions.
CutoverGrid maps migration impact, compares execution strategies, sequences migration waves, and verifies the gates required for a controlled production cutover.